





Offline evals
Contents
Offline evals test your AI agent against known inputs before you ship a prompt, model, or code change. Run your agent and score its outputs locally or in your CI, using your existing test framework. The PostHog SDK uploads the results so you can compare runs and inspect failures.
Online evaluations help you find failures in production. Add those failures to your offline test set to check that your next change fixes them.
How offline evals work
Each run follows four steps:
- Choose test cases – Each case has an input and, optionally, an expected output. Keep them in your code, a file, or a PostHog dataset.
- Run your agent – An experiment is one run of your test cases. Each experiment item holds one case's input, actual output, and expected output.
- Score the output – Use code checks, an LLM judge, or your existing evaluation library.
- Upload the results – Send the items and scores to PostHog, then mark the experiment complete.
A scorer defines what a result means: its name, value type, and passing rule. A reported scorer records scores calculated by your evaluation code and reported to PostHog, such as whether your agent selected the expected tool. With a composite scorer, PostHog calculates a score from other reported scores for the same item.
Run your first experiment
This example checks the tool and arguments a support agent selects for six requests. It uses local routing rules, so you don't need a model API key or external tools.
Three deliberate mistakes give you failures to inspect: a wrong tool, a missing order ID, and an incorrect order ID. After trying the demo, replace run_agent() / runAgent() with your agent and adapt evaluate_answer() / evaluateAnswer() to your checks.
1. Install the SDK and configure access
Install the latest SDK. This quickstart requires:
- Python: Python 3.10+ and
posthog7.74.0+. - TypeScript: Node.js matching
^20.20.0 || >=22.22.0and@posthog/ai8.16.0+.
This walkthrough uses a personal API key to create and read scorers. Experiments you create with it are attributed to your PostHog user. For uploads from your CI, use a project secret API key, which isn't tied to a person. See Use results in your CI.
Create a personal API key with access to your project and these scopes:
| Scope | Used for |
|---|---|
offline_evaluation_ingestion:write | Creating experiments, uploading results, and completing runs |
llm_analytics:read | Reading an existing scorer |
llm_analytics:write | Creating the scorer in the next step |
dataset:read | Reading a PostHog dataset, if you use one later |
Set these environment variables in your terminal or your CI secrets:
Find your project ID in project settings. For an EU project, set POSTHOG_HOST to https://eu.posthog.com.
Keep your API key in an environment variable or your CI's secret store. Never commit it or expose it in browser code. Your public project token can't authenticate these requests.
2. Create two scorers
Save this as create_scorers.py or create_scorers.mts and run it once to create Correct tool and Correct arguments. For both scorers, true passes and false fails.
Save the two printed scorer IDs. The run script fetches each scorer once and uses its current version for every case:
Reuse these scorers across experiments to keep their history together. To compare runs against a fixed configuration, save the version IDs (current_version_id / currentVersionId) instead of fetching the latest versions.
3. Run the cases and upload scores
Save this as support_eval.py or support_eval.mts. It uploads two scores per case, each with an explanation. The argument check compares exact key-value pairs independently of the tool name, so a case can pass one check and fail the other.
Run the script with the environment variables from the previous steps:
Open Experiments and select Support agent baseline. You should see six items and twelve results. Correct tool passes five of six cases (83.33%), and Correct arguments passes four of six (66.67%).
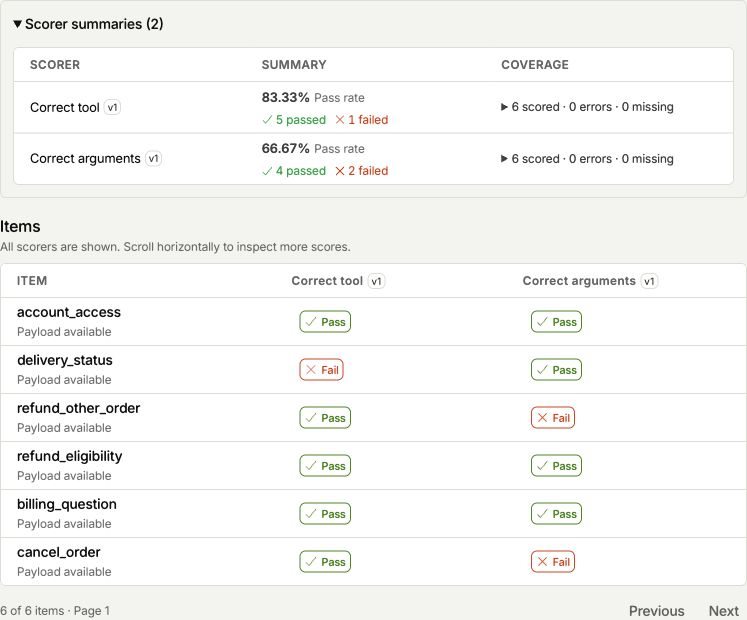
- 1Click Fail to inspect this argument check.
Keep suite_key / suiteKey the same across runs of a test suite and case_key / caseKey the same for each test case. To repeat a case within one run, create a new EvaluationItem with the same case key and a distinct trial, such as "1" or "2".
Call complete() after the uploads succeed, or fail() if the run stops early. Closing the SDK client only releases connections; it doesn't complete the experiment.
Review and compare experiments
Open AI Evals > Offline evals > Experiments:
- Select Completed in the upload-state filter to exclude runs that are still uploading or failed before all results arrived.
- Click Choose scores to select the scorers shown in Score trends. Open a scorer's history to inspect its versions and the experiments behind the trend.
- Select Support agent baseline. Each row is an experiment item, and each scorer version has its own column.
- Click Fail under Correct arguments for
refund_other_order. The inspector shows why: the agent selected the right tool but passed order ID1001instead of1004.
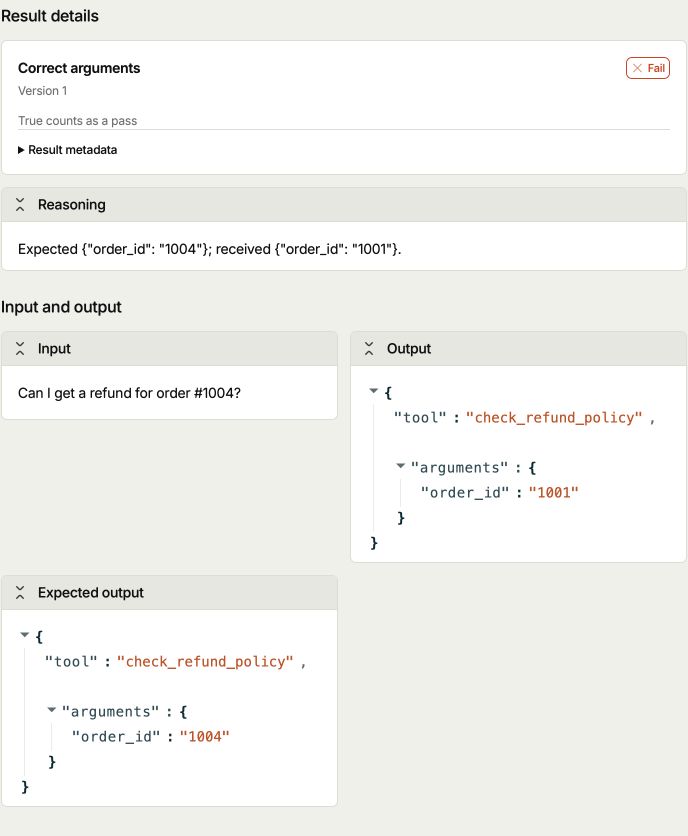
- 1Expected order 1004; received order 1001.
To fix the demo, pass the extracted order ID to the cancellation and refund tools, and return look_up_order for delivery questions. Run the same cases again with the experiment name Support agent routing fix. Both scorers should pass all six cases.
Compare runs with the same test cases and scorer versions so changes in the test don't hide changes in your agent.
Read scores alongside coverage
Pass rate includes only results with status ok. Eight passing results and two evaluator errors produce a 100% pass rate, with only eight scored items.
Expand Coverage beside each scorer summary to check errors, skipped checks, and missing results. Missing means an uploaded item has no result for that scorer. It can't reveal cases you never uploaded, so compare the received item count with your expected count too. Composite calculations you haven't requested show Not requested.
Numeric scorers show their mean. Numeric and categorical scorers need a passing rule to show a pass rate. Repeated trials each count as an item, so keep trial counts consistent when comparing runs.
Use results in your CI
Use a project secret API key with the offline_evaluation_ingestion:write scope for your CI uploads. It can create experiments, upload results, and mark runs complete or failed without depending on a teammate's account.
Project secret keys can't create or read scorers or fetch datasets. Set up scorers and load any PostHog dataset with a personal key first. In your CI script, pass the project key as secret_key / secretKey and use saved scorer version IDs instead of calling scorers.get().
For a composite, save its version ID and the exact input versions it pins. Send those input results with each calculation request.
In your CI, set run_source="ci" in Python or runSource: "ci" in TypeScript. Record your agent's commit SHA in application_version or applicationVersion. You can also record model_version and prompt_version (modelVersion and promptVersion in TypeScript).
For runs that use multiple models, set model_version / modelVersion on each EvaluationItem to override the experiment's model. This requires posthog 7.76.0+ or @posthog/ai 8.17.0+.
Completing an experiment means the run finished, not that every case passed. To block a deployment, check scores against your own threshold in the test script and exit with a failure code.
Use a PostHog dataset (optional)
Use a PostHog dataset to manage cases in PostHog or save them from production traces. This example loads a dataset revision before starting the experiment.
To try it with the demo, create dataset items with string inputs and expected outputs containing tool and arguments, as in the cases above. Set POSTHOG_DATASET_ID to your dataset's ID and replace the experiment creation and loop in the previous example. Keep the same client, scorers, agent, evaluator, error handling, and final complete() call.
from_dataset_item() / fromDatasetItem() copies the test case and its version into the experiment item. Always supply the new run's output. The dataset's source_output is an earlier answer.
By default, snapshot() selects the latest revision when you call it. To repeat an earlier test set, pass revision=12 in Python or { revision: 12 } as the second argument in TypeScript. The revision must still be available under the dataset retention policy.
Add more scores
Use a separate scorer for each thing you want to measure, such as correctness, relevance, or whether the agent selected the right tool.
| Scorer type | Result value | Example |
|---|---|---|
| Boolean | true or false | Did the agent complete the task correctly? |
| Numeric | A number | How relevant is the answer, from zero to five? |
| Categorical | A list of category keys | Which failure types occurred, such as ["wrong_tool"]? |
Create scorers with the SDK or in Scorers. Each result references a fixed scorer version, so configuration changes don't reinterpret earlier results.
For each additional reported score, call upload_result() / uploadResult() with the same EvaluationItem and the new scorer's version ID. Include all reported and composite results in your expected result count.
Use reasoning to explain a score. Set application_trace_id / applicationTraceId on the item to link it to an AI Observability trace.
Failed checks and evaluator errors
Use value=False / value: false for a failed check. The default status, ok, means the evaluator produced a score, not that the item passed.
If the evaluator can't produce a score, upload status="error" / status: "error", omit value, and include an error_message / errorMessage. Use skipped for a check you didn't run, or not_applicable when a scorer doesn't apply to an item.
Combine scores with a composite scorer
A composite scorer combines reported scores for one item into a boolean, numeric, or categorical result.
For the support-agent example, Support task passed requires both Correct tool and Correct arguments to pass. Three of the six cases pass both checks, giving a 50% pass rate.
Create the composite
Use the latest SDK. Save this as create_composite.py or create_composite.mts and run it once with the quickstart's environment variables and existing scorers.
Save the printed scorer ID:
You can also create this scorer in Scorers. Choose Composite formula and Boolean, add the two input scorers, and set their Formula name fields to tool_correct and arguments_correct. Use tool_correct and arguments_correct as the formula and True means pass as the passing value.
Each input uses a fixed scorer version. New input versions don't update the composite automatically. Changing its formula or inputs creates a new composite version; existing results stay unchanged.
Request a calculation for each item
Upload the reported inputs and a calculation request together for each item. Creating the scorer alone doesn't calculate results.
In support_eval.py or support_eval.mts, add EvaluationResult to the SDK imports. Keep the agent, evaluator, and cases, then replace the client block below them with this code. It uses the input versions saved in the composite.
For a composite result, send only the item, scorer version, and calculate=True / calculate: true. PostHog calculates the value. Check each returned status and error_code / errorCode: an upload can succeed while a calculation fails.
This run expects 18 results: twelve reported and six composite. Accepted errors and skipped results count toward the total. Start a new experiment to test another composite version; completed runs can't accept new results.
Sending the inputs and calculation together works with the quickstart's permissions, including on retries. To reuse previously uploaded inputs, also grant evaluation:read and llm_analytics:read. For larger batches, keep each item's results together so the SDK can send them in one request.
Open the experiment to see Support task passed alongside the two reported scorers. Items without a calculation request show Not requested and don't affect its pass rate.
Write formulas
These formulas use the two boolean inputs from the support-agent example:
| Output | Formula | Meaning |
|---|---|---|
| Boolean | tool_correct and arguments_correct | Pass only when both checks are true. |
| Numeric | (number(tool_correct) + number(arguments_correct)) / 2 | Return 0, 0.5, or 1 for each item. |
| Categorical | "pass" if tool_correct and arguments_correct else "fail" | Return a category key configured on the composite. |
Formulas read raw input values. number(True) is 1 and number(False) is 0, even if an input scorer treats true as a failure. For categorical inputs, test category keys with expressions such as "helpful" in relevance.
In the UI, the formula editor suggests a formula from the output type and inputs' passing rules. Manual edits stay unchanged when you edit inputs. Click Use default formula to restore the suggestion.
You can use arithmetic (+, -, *, /), comparisons, and, or, not, conditional expressions, and the number, min, max, and abs functions. Each formula can reference up to 16 reported scorer versions. Every selected input must appear in the formula. Composite scorers can't use other composites as inputs or combine results across different items.
Handle missing inputs and calculation errors
If a pinned input result is missing, PostHog rejects the entire upload request. Include that input for the same item and version when you retry.
If an input has status error, skipped, or not_applicable, the composite inherits that status without a value. If several statuses apply, the order is error, then skipped, then not_applicable. Input errors use the code composite_input_error.
A calculation error, such as division by zero or a value outside the composite's configured bounds, produces an error result with code composite_formula_error. Valid reported inputs in the same request are still saved. These errors don't enter the composite's mean or pass rate.
Use MCP
Use the PostHog MCP server to create scorers, manage datasets, and upload experiments from your AI agent. For composites, include the pinned inputs and a calculate: true request for each item.
Data retention
PostHog deletes evaluation payloads 30 days after first accepting them:
| Data | Retention |
|---|---|
| Item inputs, actual outputs, expected outputs, and payload metadata | Deleted after 30 days |
| Result reasoning, error messages, and payload metadata | Deleted after 30 days |
| Experiment, item, and result records, including scores, statuses, summaries, and trends | Kept |
Keep your own copy of payloads you need after 30 days. Source datasets have their own retention policy.
Pricing
Each newly accepted reported scorer result for one experiment item counts as one AI Observability event. This includes reported results with status error, skipped, or not_applicable. Retrying the same result doesn't add another event.
Calculated composite results don't add billed events. For example, the six support-agent cases with two reported scorers and one composite produce 18 results and count as 12 events.
Offline evals share the AI Observability event pricing and free tier with your other AI Observability events. They don't have a separate free allowance.