

The best Braintrust alternatives & competitors, compared


Contents
Braintrust built a fast, popular, and reliable eval-first platform good enough that Notion, Vercel, and Cloudflare all use it. If evals are your whole problem, you could do a lot worse.
But evals usually aren't the whole problem. Maybe you hit the free tier's limit and discovered the next step is $249/month, no middle rung. Maybe you asked about self-hosting and got routed to Enterprise sales. Or maybe you realized "the eval passed" and "the user was happy" are two different metrics, and Braintrust only tracks one of them.
This guide breaks down the strongest Braintrust alternatives: what each does well, where it comes up short, and which teams it serves best.
1. PostHog
- Founded: 2020
- Similar to: Braintrust, Langfuse, LangSmith
- Typical users: Engineers and product teams building AI features
- Typical customers: Mid-size B2Bs and startups
What is PostHog?
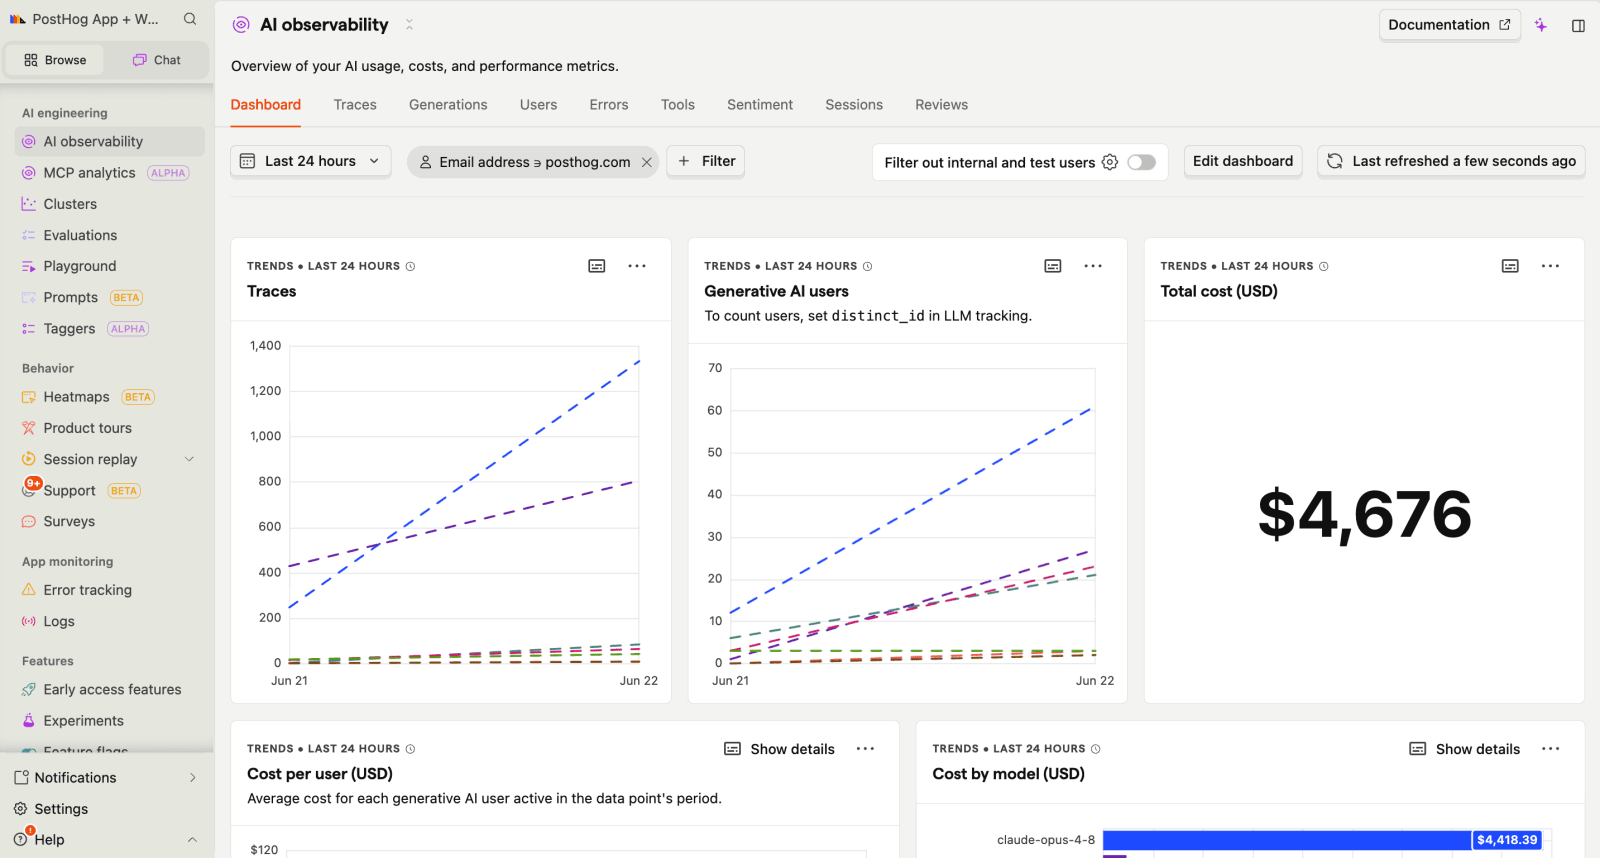
PostHog (that's us 👋) is the leading platform for self-driving products. You can use our Desktop, web, Slack, and MCP products to leverage tools like AI observability, product analytics, session replay, feature flags, experiments, error tracking, logs, and more.
PostHog captures full traces of your LLM calls, so you can follow a request through every prompt, tool call, and model response. For each generation, it tracks token usage, cost, latency, and errors, and you can score outputs with LLM-as-a-judge or code-based evals to catch quality regressions.
You can also manage and version prompts without redeploying code, and query trace data with SQL or through the MCP server directly from your editor.
The difference from Braintrust is what surrounds the traces. Braintrust is laser focused on evals. PostHog expands on what comes after that: the model shipped, so now what?
Because traces are regular PostHog events, you can watch the session replay of a confused user's AI interaction, check whether people who hit slow generations churn, gate a new model behind a feature flag, and A/B test whether the new prompt actually improved activation.
Key features
AI evals: Automatically score model outputs using LLM-as-a-judge or code-based checks to track quality and identify regressions over time.
Generations: Monitor model performance, token usage, costs, latency, and errors across your AI features from a single view.
Traces: Follow AI workflows from start to finish to understand how requests move through prompts, tools, and model calls.
Prompt management: Create, version, and update prompts without redeploying code. Compare versions and understand how prompt changes affect outputs.
SQL access: Query AI observability data with SQL and analyze it alongside product, user, and business data.
Session replay: Watch recordings of users interacting with AI features and investigate issues alongside the actions that triggered them.
PostHog AI: Query your data in plain English, build dashboards, write SQL, and create insights by having a conversation instead of clicking through menus.
How does PostHog compare to Braintrust?
Main differences between PostHog and Braintrust
- Braintrust is eval-first: CI-integrated quality gates, dataset curation, and deployment blocking are the core workflow. PostHog supports evals, but they're one feature in a broader platform.
- PostHog connects LLM data to product analytics, session replay, feature flags, error tracking, and more. Braintrust has none of these.
- They bill differently: Braintrust charges by processed data (1 GB free, then $249/month for 5 GB), while PostHog charges per event (100K AI events free, then usage-based).
- Braintrust's free tier retains data for 14 days. PostHog's free tier retains event data for 30 days.
- PostHog is MIT-licensed and open source. Braintrust is closed-source, with self-hosting available on Enterprise only.
Main similarities between PostHog and Braintrust
- Both capture LLM traces with inputs, outputs, token usage, cost, and latency.
- Both offer prompt management with versioning and a playground.
- Both support LLM-as-a-judge and code-based evaluation.
- Both have usage-based pricing with a free tier.
- Both support OpenAI, Anthropic, and other major LLM providers.
Why do companies use PostHog?
According to reviews on G2, companies use PostHog because:
It replaces several tools: PostHog combines LLM observability, product analytics, session replay, feature flags, and error tracking into a single platform, so you do not need to use multiple separate tools.
Pricing is clear and scalable: PostHog uses usage-based pricing with no per-seat charges and a generous free tier. Eligible startups can also receive an additional $50,000 in free credits.
It connects AI performance to user behavior: Teams see not just what their LLM is doing, but how users interact with AI features, where they drop off, what drives retention, and how prompt changes affect product metrics.
Bottom line
PostHog is the best Braintrust alternative for teams that want AI observability integrated into the full product development stack. If you want to track LLM performance, prompt changes, and user behavior in one place, PostHog is the strongest option on this list.
Install PostHog with one command
Paste this into your terminal and make AI do all the work.
2. Langfuse
- Founded: 2022
- Similar to: Braintrust, LangSmith, Arize Phoenix
- Typical users: Engineers building and debugging LLM applications and agents
- Typical customers: Startups and enterprises with strict data residency requirements
What is Langfuse?
Acquired by ClickHouse in January 2026, Langfuse is an open source LLM engineering platform covering observability, prompt management, and evaluation.
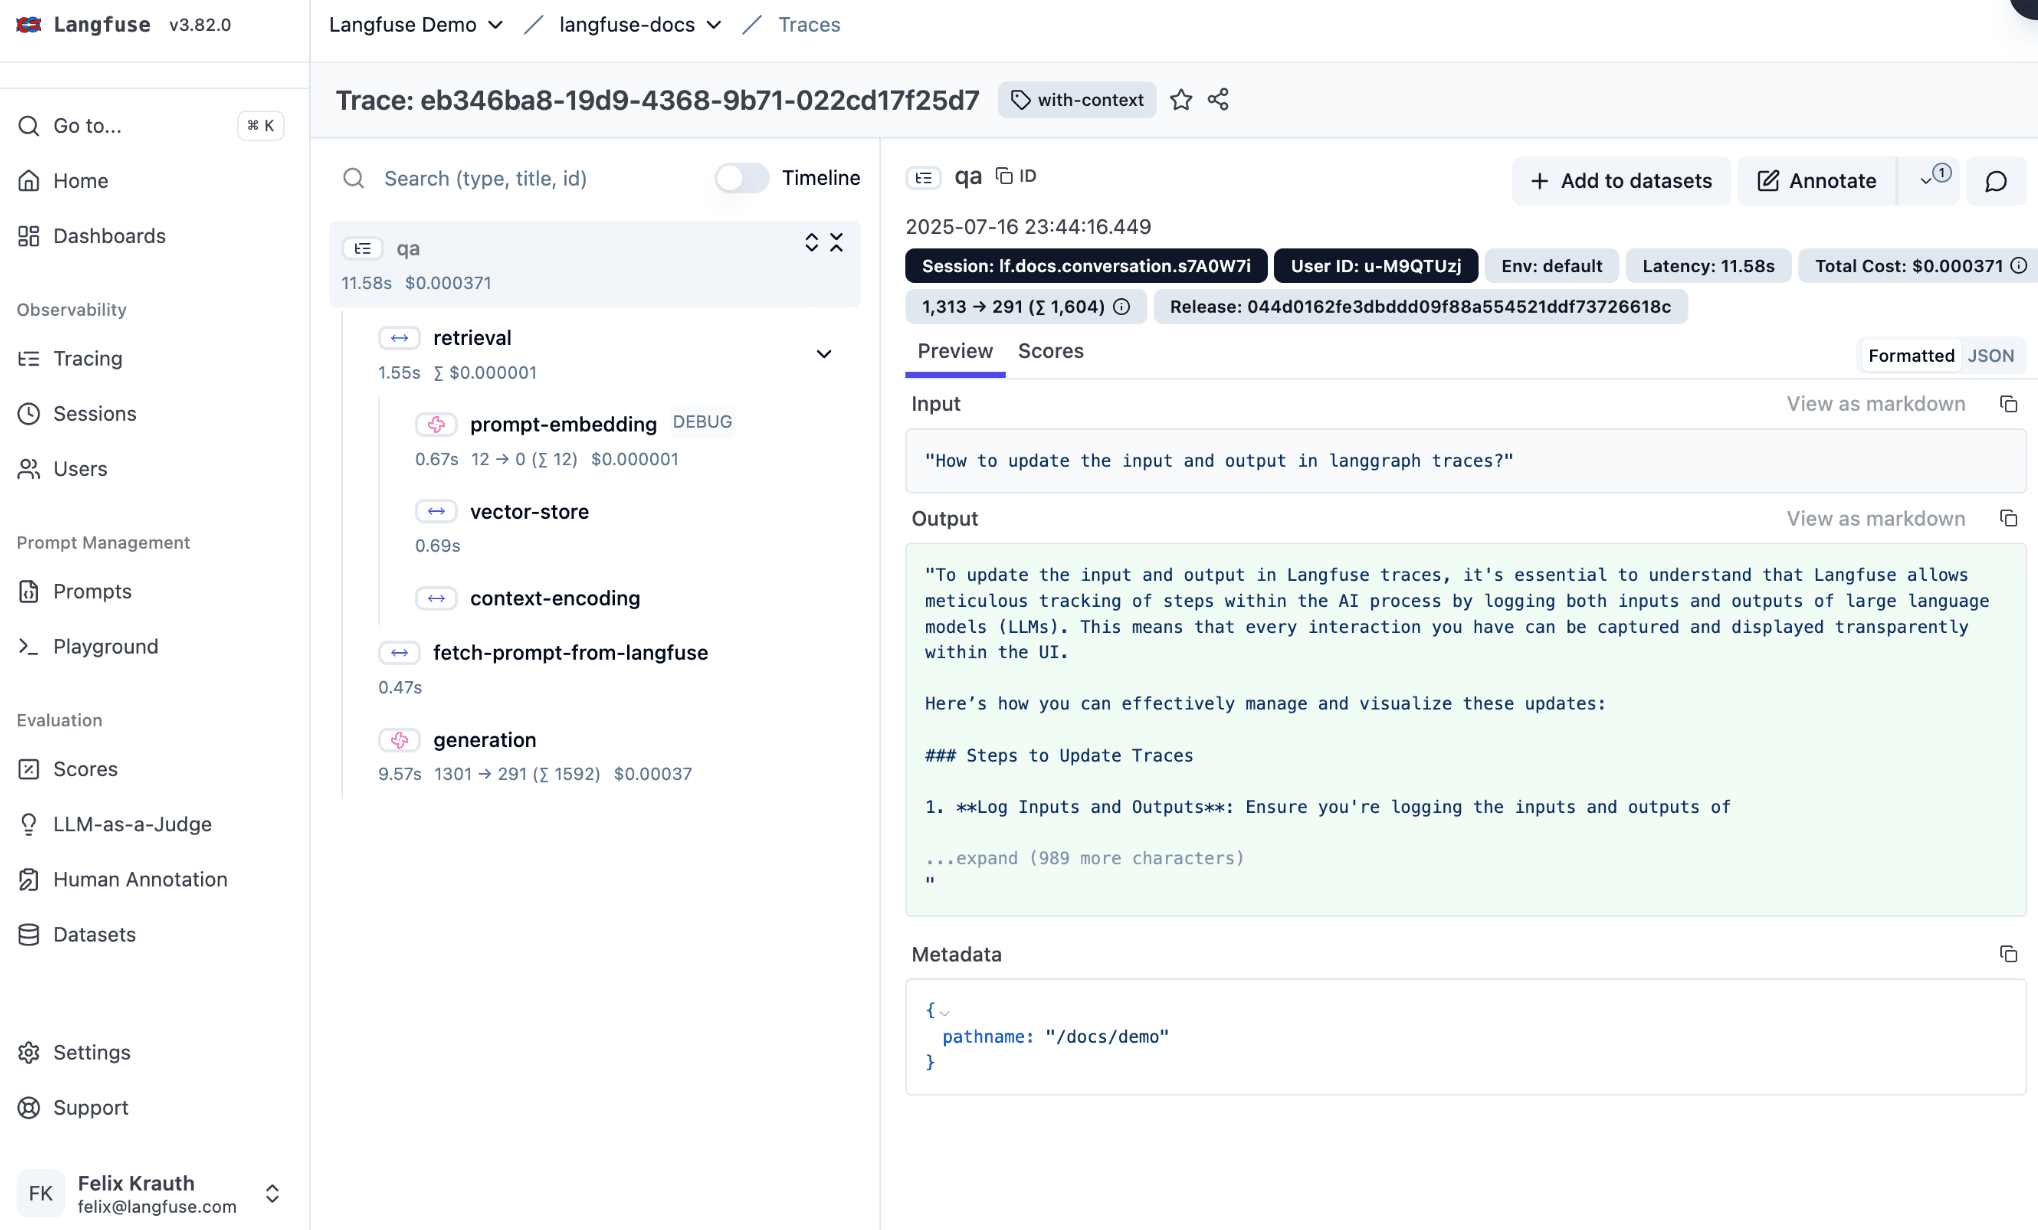
Langfuse captures detailed traces of LLM calls with spans, observations, and metrics across any framework or provider. Its SDK is built on the official OpenTelemetry client, so token usage, cost tracking, and prompt linking work with any OTel-compatible library out of the box.
On top of tracing, it layers prompt management with one-click rollbacks, evaluations via LLM-as-a-judge, heuristics, or human review, and CI/CD experiment actions for catching quality regressions in your pipeline.
Against Braintrust specifically, Langfuse takes a similar approach to licensing: what Braintrust gates behind an Enterprise contract (self-hosting, full data control) is Langfuse's default. On the other hand, Braintrust's eval loop is more tightly integrated out of the box, while Langfuse's equivalent workflows take more configuration to assemble.
Key features
LLM tracing: Every LLM call, tool execution, and retrieval step is recorded with full input/output capture, cost, latency, and token usage.
Prompt management: Version-control prompts and test changes in the built-in playground before pushing to production.
Evaluations: Score outputs automatically or route them to human reviewers, with dataset management for tracking quality over time.
CI/CD experiments: Catch prompt and model quality regressions in your pipeline before they reach production.
Metrics and analytics: Monitor usage, cost, latency, and quality trends across your application with custom dashboards.
Integrations: Works with LangChain, LlamaIndex, Vercel AI SDK, OpenTelemetry, and most major LLM frameworks out of the box.
How does Langfuse compare to Braintrust?
Main differences between Langfuse and Braintrust
- Langfuse is MIT-licensed and fully self-hostable by anyone. Braintrust is closed-source, with self-hosting available only on Enterprise.
- Langfuse has native integrations for more frameworks than Braintrust, including non-LangChain stacks like PydanticAI, Vercel AI SDK, and OpenTelemetry-based custom stacks.
- Braintrust's Brainstore database is purpose-built for AI trace queries. Langfuse runs on ClickHouse, which is powerful but requires more infrastructure management at scale when self-hosted.
- Braintrust's free tier includes 1GB of processed data. Langfuse's Hobby plan includes 50,000 units/month.
Main similarities between Langfuse and Braintrust
- Both offer LLM tracing with inputs, outputs, token usage, cost, and latency per span.
- Both support prompt versioning and management.
- Both have LLM-as-judge evaluation and dataset management.
- Both support CI/CD-integrated eval workflows.
- Both have a free tier and usage-based pricing with no per-seat charges.
Why do companies use Langfuse?
According to reviews on Product Hunt and Gartner Peer Insights, companies use Langfuse because:
It removes blind spots in agent workflows: Detailed tracing is critical for understanding which context is pulled into agent workflows and how decisions are made at every step.
Self-hosting is a first-class option: The open-source, self-hosted path means data never leaves your own infrastructure, without sacrificing enterprise-grade observability.
It has the most detailed latency and analytics: Reviewers recommend it for complex chains or user-facing chat applications where latency visibility is critical.
Bottom line
Langfuse is the strongest open-source Braintrust alternative for teams that want full control over their data and infrastructure, broad framework support, and a self-hosted path that doesn't require an enterprise contract.
3. LangSmith
- Founded: 2023
- Similar to: Braintrust, Langfuse, Arize Phoenix
- Typical users: Engineers building and deploying LLM applications and agents
- Typical customers: Startups and enterprises shipping production LLM applications
What is LangSmith?
LangSmith is the observability and evaluation platform from the LangChain team.
Both LangSmith and Braintrust are closed-source platforms with CI-integrated quality gates; the difference is LangSmith is anchored to the LangChain ecosystem, enabling zero-config tracing, node-by-node state diffs, and native agent execution trees.
LangSmith also covers the full eval workflow: LLM-as-a-judge and code-based scoring against production traces, annotation queues for human review, dataset management, and CI/CD regression testing via GitHub Actions.
The main structural difference from Braintrust is pricing: LangSmith charges $39 per seat per month on paid plans, so costs scale with headcount. Braintrust's Pro plan is $249/month flat with no per-seat fees – cheaper for large teams, pricier for a two-person startup.
Key features
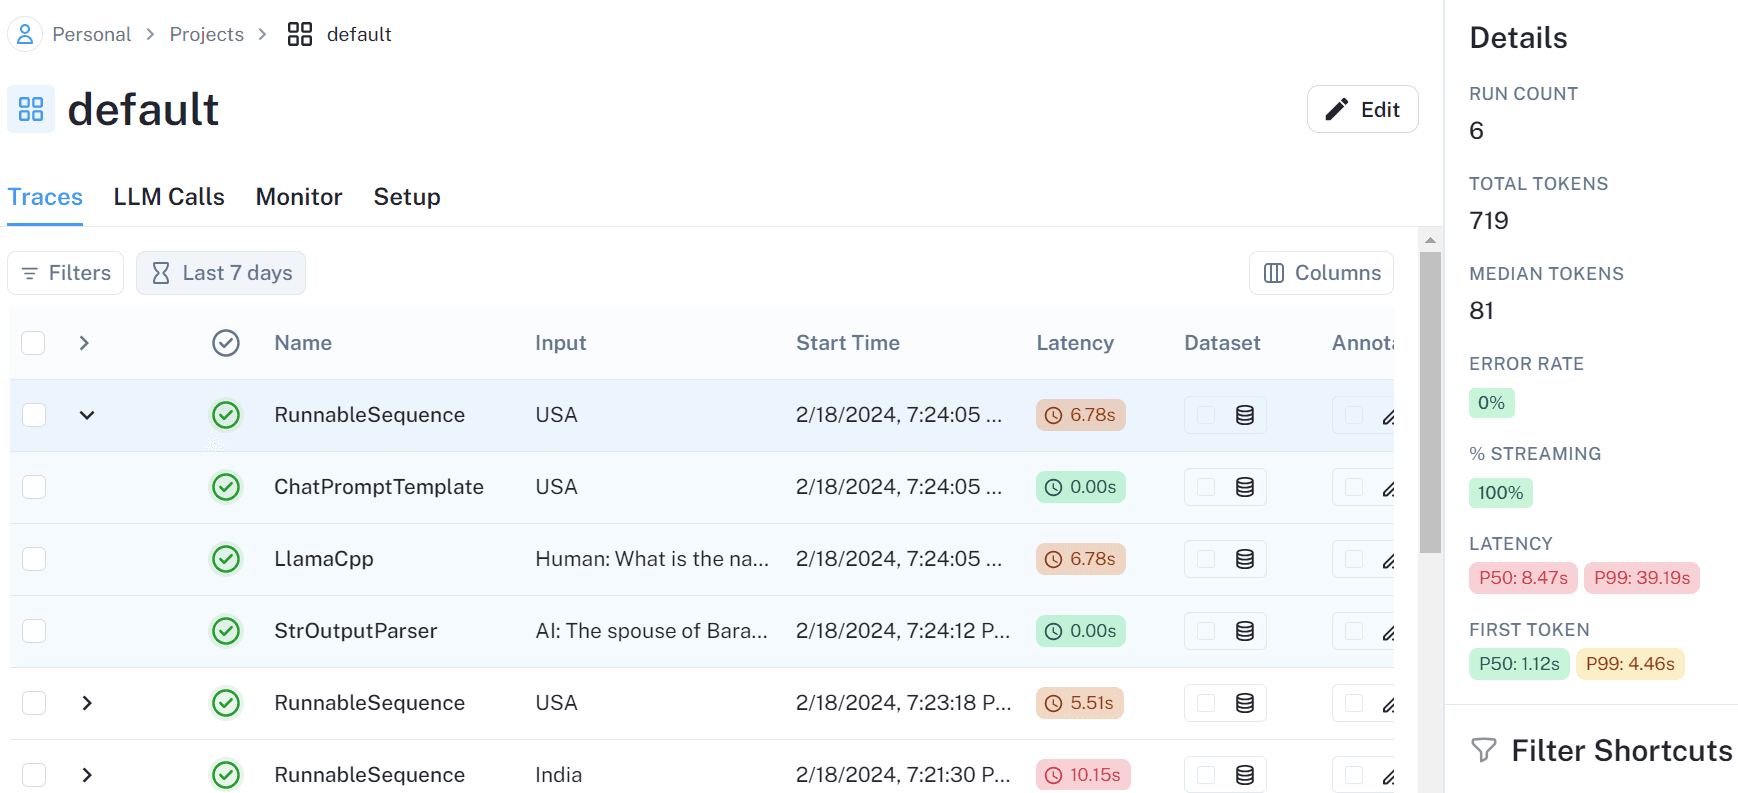
Agent tracing: See exactly what your agent did at every step, including inputs, outputs, tool calls, cost, and latency, with full execution tree visualization.
Cost monitoring: Unified spend visibility across LLM calls, tool executions, retrieval steps, and third-party APIs in one view.
Evaluations: LLM-as-judge and code-based scoring against production traces, with annotation queues for human review.
CI/CD regression testing: Automate eval runs on every pull request via GitHub Actions to block regressions before they reach production.
LangSmith Fleet: Build, test, and deploy agents directly from LangSmith using its managed deployment service.
Prompt management: Run side-by-side playground comparisons and push versioned prompt changes without touching your codebase.
How does LangSmith compare to Braintrust?
Main differences between LangSmith and Braintrust
- LangSmith's deepest features are designed for LangChain and LangGraph. Braintrust is framework-agnostic.
- Braintrust uses Brainstore, a purpose-built AI trace database. LangSmith runs on standard cloud infrastructure.
- LangSmith's free tier includes 5k traces/month. Braintrust includes 1GB of processed data/month.
- LangSmith has per-seat pricing on paid plans at $39/seat/month. Braintrust's Pro plan is $249/month flat with unlimited seats.
- LangSmith includes a managed agent deployment service. Braintrust does not.
Main similarities between LangSmith and Braintrust
- Both support CI-integrated eval workflows with GitHub Actions.
- Both offer LLM-as-judge evaluation, human annotation queues, and dataset management.
- Both capture full LLM traces with inputs, outputs, token usage, cost, and latency.
- Both have prompt management and version control.
- Both have a free tier and usage-based pricing.
Why do companies use LangSmith?
According to reviews on Gartner Peer Insights, companies use LangSmith because:
Removes the guesswork from production debugging: Every model response is visible step by step, making it easier to catch and fix issues before they compound.
Full visibility into agent behavior: Every agent action and trace is captured, making it straightforward to monitor behavior and ensure consistency in production.
Significantly shorter debugging cycles: A LangSmith customer story showed that Klarna reduced customer resolution times by 80% after adoption.
Bottom line
LangSmith is the strongest Braintrust alternative for teams already using LangChain or LangGraph. Outside that ecosystem, their limited free tier makes other tools on this list more appealing.
4. Arize Phoenix
- Founded: 2020
- Similar to: Braintrust, Langfuse, LangSmith
- Typical users: AI engineers and data scientists building and monitoring LLM applications
- Typical customers: Enterprise teams running both traditional ML and LLM workloads
What is Arize Phoenix?
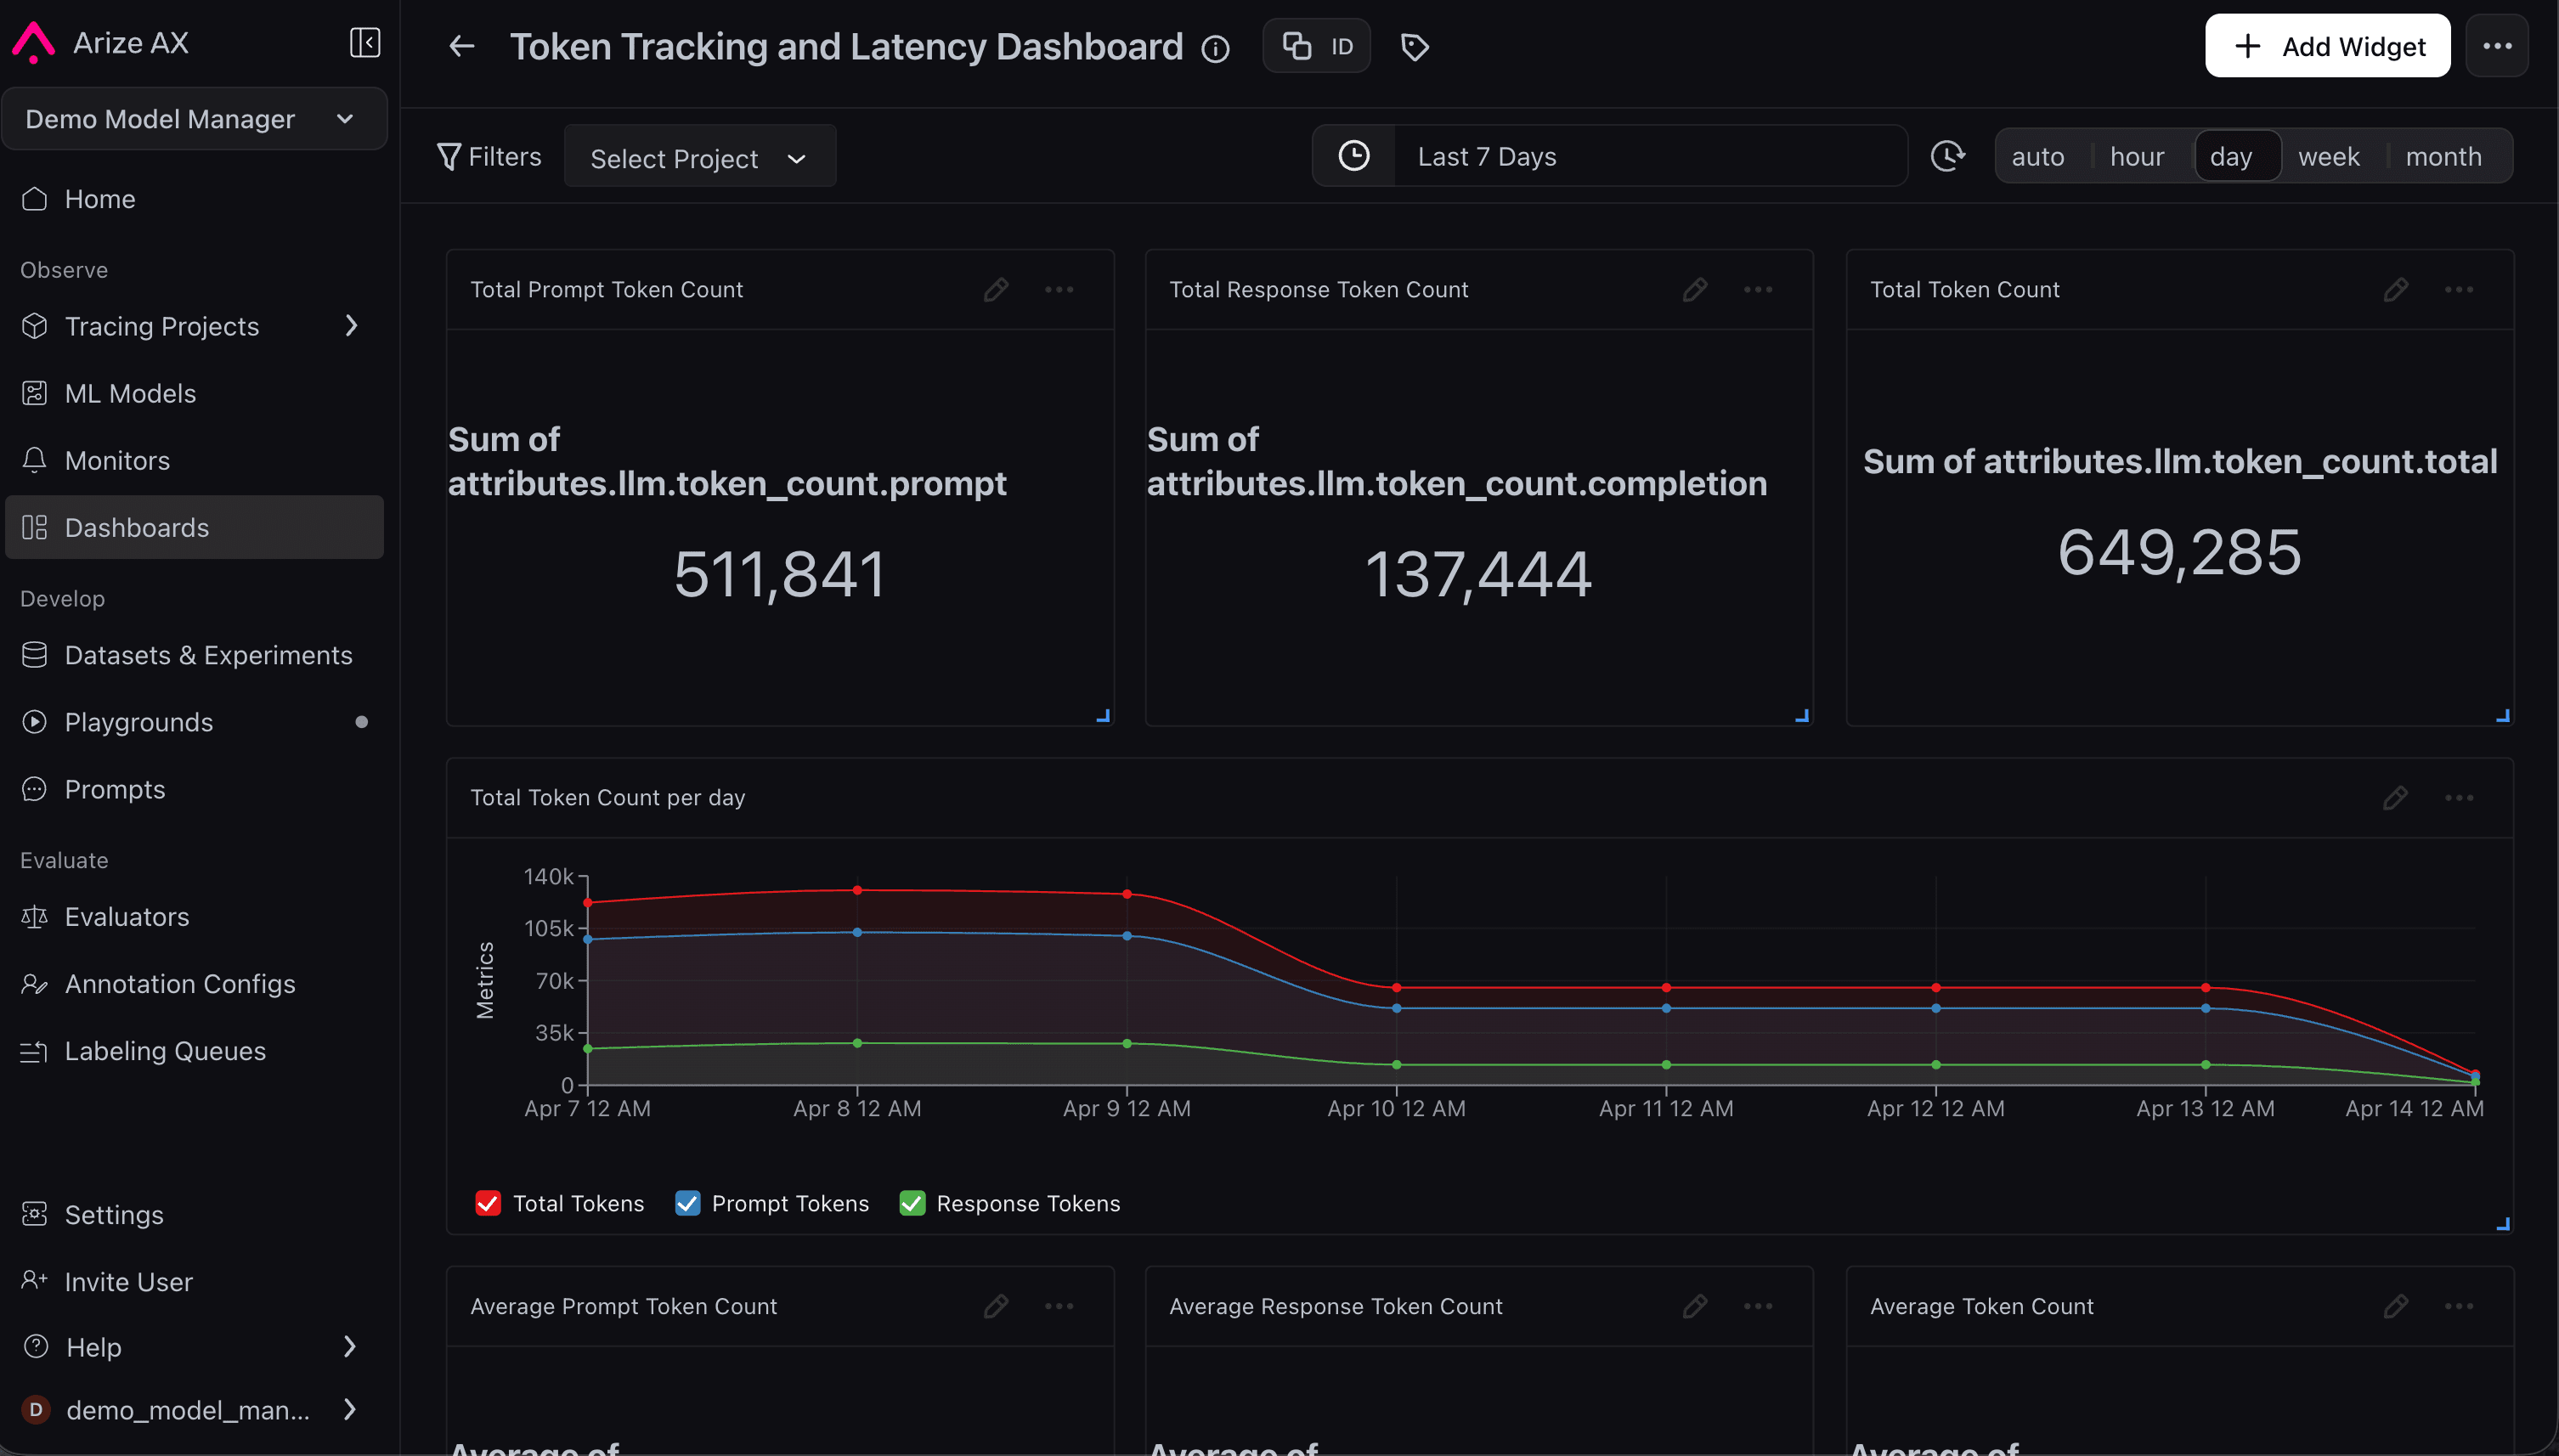
Arize Phoenix is a source-available LLM observability and evaluation platform built by Arize AI. Built on the OpenTelemetry and OpenInference open standards, traces are never locked into a proprietary format, and data can be routed to other backends such as Jaeger, Prometheus, or Grafana without switching tools. They were acquired by Dynatrace in August 2026.
It ships research-backed evaluators for hallucination, faithfulness, relevance, and toxicity out of the box, plus dataset experiments, a prompt playground, and a versioned Evaluator Hub.
Braintrust built a proprietary database around a proprietary trace format – fast, but your data lives in its shape. Phoenix bets the other way: open standards, free self-hosting, and an exit path built into the architecture.
When teams need enterprise production monitoring – or traditional ML and LLM monitoring on one platform – Arize AX is the commercial upgrade path, with no instrumentation changes required.
Key features
LLM tracing: Get full visibility into every generation, tool call, and retrieval step with inputs, outputs, cost, latency, and token counts.
Evaluations: Assess output quality through LLM-as-judge, code-based evaluators, or human reviewers via a versioned Evaluator Hub.
Dataset experiments: Pull datasets from production traces and measure how prompt or model changes affect quality before shipping.
Prompt playground: Iterate on prompts using real production examples across multiple model providers.
OpenTelemetry-native: Traces follow open standards with no proprietary format lock-in across major AI frameworks.
Self-hosting: Deploy Phoenix on your own infrastructure with full feature access and complete data isolation.
How does Arize Phoenix compare to Braintrust?
Main differences between Arize Phoenix and Braintrust
- Phoenix is source-available under Elastic License 2.0 and free to self-host with no feature limitations. Braintrust is closed-source, with self-hosting available on Enterprise only.
- Braintrust's eval loop is more tightly integrated: one-click trace-to-dataset, AI-assisted scorer generation via Loop, and native PR gating. Phoenix's evaluators are strong but assembling the same workflow takes more wiring.
- Phoenix is built on OpenTelemetry open standards. Braintrust uses a proprietary trace format with Brainstore.
- Arize AX adds traditional ML and computer vision monitoring. Braintrust is LLM-only.
Main similarities between Arize Phoenix and Braintrust
- Both offer LLM tracing with inputs, outputs, token usage, cost, and latency.
- Both support LLM-as-judge evaluation and dataset management.
- Both have prompt management and a playground for testing changes.
- Both have a free tier and support OpenAI, Anthropic, and other major providers.
- Both support CI/CD integration for running evaluations.
Why do companies use Arize Phoenix?
According to customer stories on Arize, companies use Arize Phoenix because:
Observability from day one: Handshake deployed and scaled 15+ LLM use cases in under six months by integrating Arize for observability and evals from the start.
Phoenix and Arize work together across the full model lifecycle: Lou Kratz, Principal Research Engineer at Bazaarvoice, noted: "We have models ranging from decision trees to convolutional neural nets and now to generative models using prompts. For all of those, we use Arize and Phoenix to measure their outcomes as well as their availability."
Non-technical stakeholders can see the value of AI directly: Arize makes it possible to report outcome statistics to dashboards, so business teams can see the value AI brings without needing to ask an engineer to dig into the data.
Bottom line
Arize Phoenix is the strongest Braintrust alternative for teams that want source-available, OTel-native LLM observability, or when both traditional ML and LLM monitoring need to live on one platform.
5. Opik by Comet
- Founded: 2024
- Similar to: Braintrust, Langfuse, LangSmith
- Typical users: AI engineers and data scientists building and monitoring LLM applications
- Typical customers: Startups and enterprises building production LLM applications and agents
What is Opik?
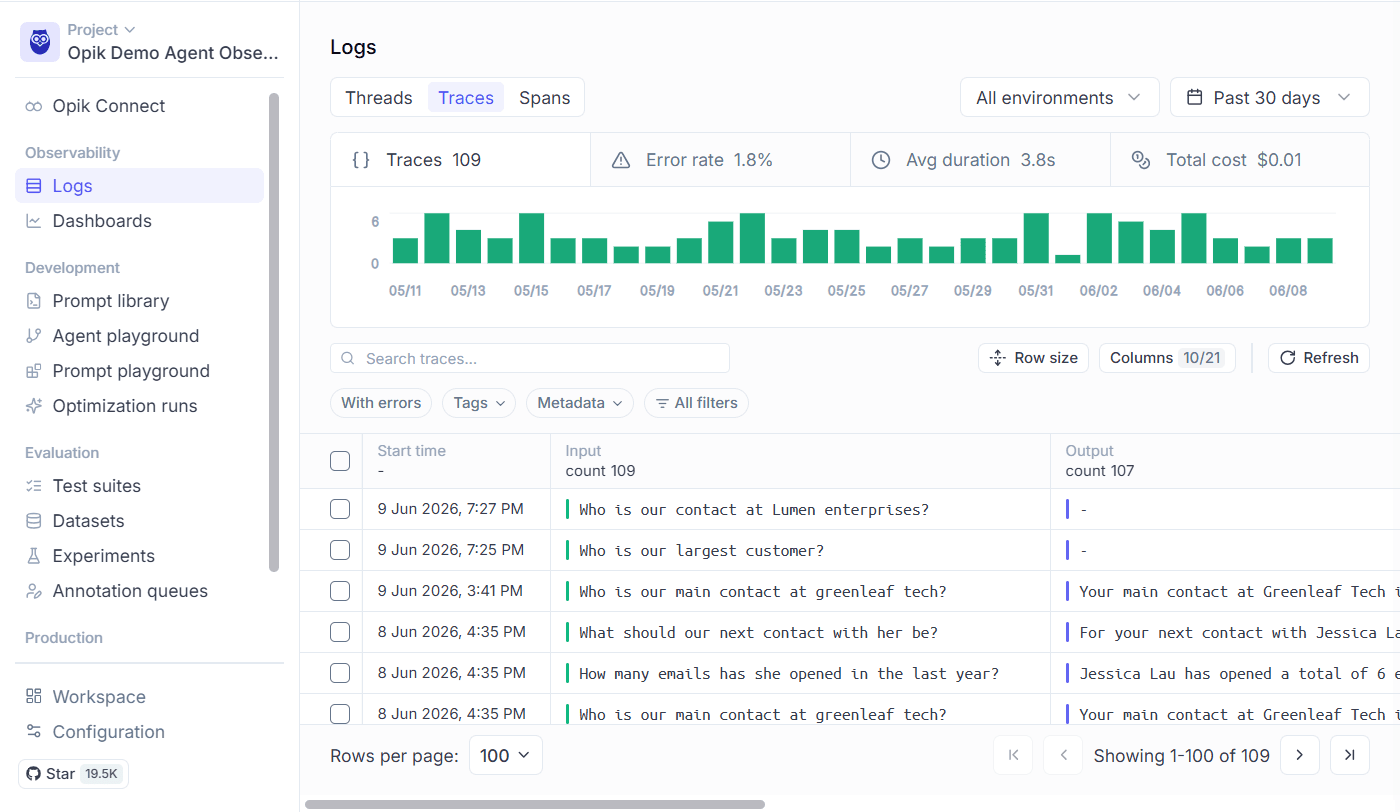
Opik is an open-source LLM observability and evaluation platform built by Comet, a company with over a decade of ML experiment tracking. It covers the full lifecycle from local experimentation to production monitoring at high trace volumes.
Opik scores production traces in real time with built-in metrics for hallucination, relevance, and task completion, routes outputs to subject-matter experts via annotation queues, and ships guardrails that screen for PII and policy violations before responses reach users.
Ollie, Opik's coding agent, analyzes traces and writes fixes directly to your codebase with a regression test for every fix. And their Agent Optimizer automates prompt tuning against your own eval data, instead of leaving it to manual trial and error.
Against Braintrust, the comparison matches Langfuse's: Apache 2.0 and fully self-hostable versus closed source with hybrid Enterprise-only self-hosting. Opik adds automation; where Braintrust's Loop suggests scorers, Ollie ships code.
Key features
LLM tracing: Capture every LLM call, tool execution, and agent step with full input/output, token counts, cost, and latency.
Evaluations: Score outputs with LLM-as-judge, built-in hallucination and relevance metrics, or custom evaluators.
Online evaluation: Automatically score production traces using real-time evaluation rules.
Prompt management: Version prompts, compare changes in the playground, and push updates without redeploying.
Agent optimization: Ollie, Opik's built-in coding agent, analyzes traces, identifies fixes, and writes them directly to your codebase.
Self-hosting: Run Opik on your own infrastructure with full feature access and no usage caps.
How does Opik compare to Braintrust?
Main differences between Opik and Braintrust
- Braintrust blocks deployments automatically when eval scores regress. Opik supports CI integration but does not offer deployment blocking.
- Opik's Ollie coding agent analyzes traces and writes fixes directly to your codebase. Braintrust has no equivalent automated optimization feature.
- Opik's free cloud tier includes 25K spans/month with unlimited team members. Braintrust's free tier includes 1GB of processed data/month.
- Opik is backed by Comet's MLOps platform for engineers running both ML experiments and LLM applications. Braintrust is LLM-only.
- Opik is Apache 2.0 open-source and fully self-hostable with no feature limitations. Braintrust is closed-source with self-hosting on Enterprise only.
Main similarities between Opik and Braintrust
- Both offer LLM tracing with inputs, outputs, token usage, cost, and latency.
- Both support LLM-as-judge evaluation and dataset management.
- Both have prompt management and CI/CD integration for running evaluations.
- Both have a free tier and usage-based pricing.
- Both support OpenAI, Anthropic, and other major LLM providers.
Why do companies use Opik?
According to customer stories, companies use Opik because:
Agent debugging stops being a black box: Zencoder's Engineering Manager noted: "We needed a solution that allowed us to see how our models behaved, and understand what went wrong, and share that with the team to debug and iterate faster."
Non-engineers can participate in evaluation: Domain experts can review LLM outputs and provide feedback directly inside the platform, closing the loop between research and product.
Cost optimization becomes measurable: Pattern's AI Ops team used Opik to run side-by-side model comparisons and identify a more cost-effective model without sacrificing performance.
Bottom line
Opik is the strongest Braintrust alternative for engineers that want a fully open-source, self-hostable LLM observability platform with real-time evaluation and automated agent optimization built in.
6. W&B Weave
- Founded: 2024
- Similar to: Braintrust, Langfuse, Opik
- Typical users: ML engineers and AI developers building and monitoring LLM applications
- Typical customers: Enterprises with both ML and LLM workloads, including OpenAI, Meta, NVIDIA, and Microsoft
What is W&B Weave?
W&B Weave is the LLM observability and evaluation product from Weights & Biases, an AI developer platform used by over one million developers worldwide.
W&B rebuilt Weave from the ground up in June 2026 to focus specifically on production agent observability. Weave now sits inside a broader ML development platform where model training, fine-tuning, and production LLM monitoring all connect.
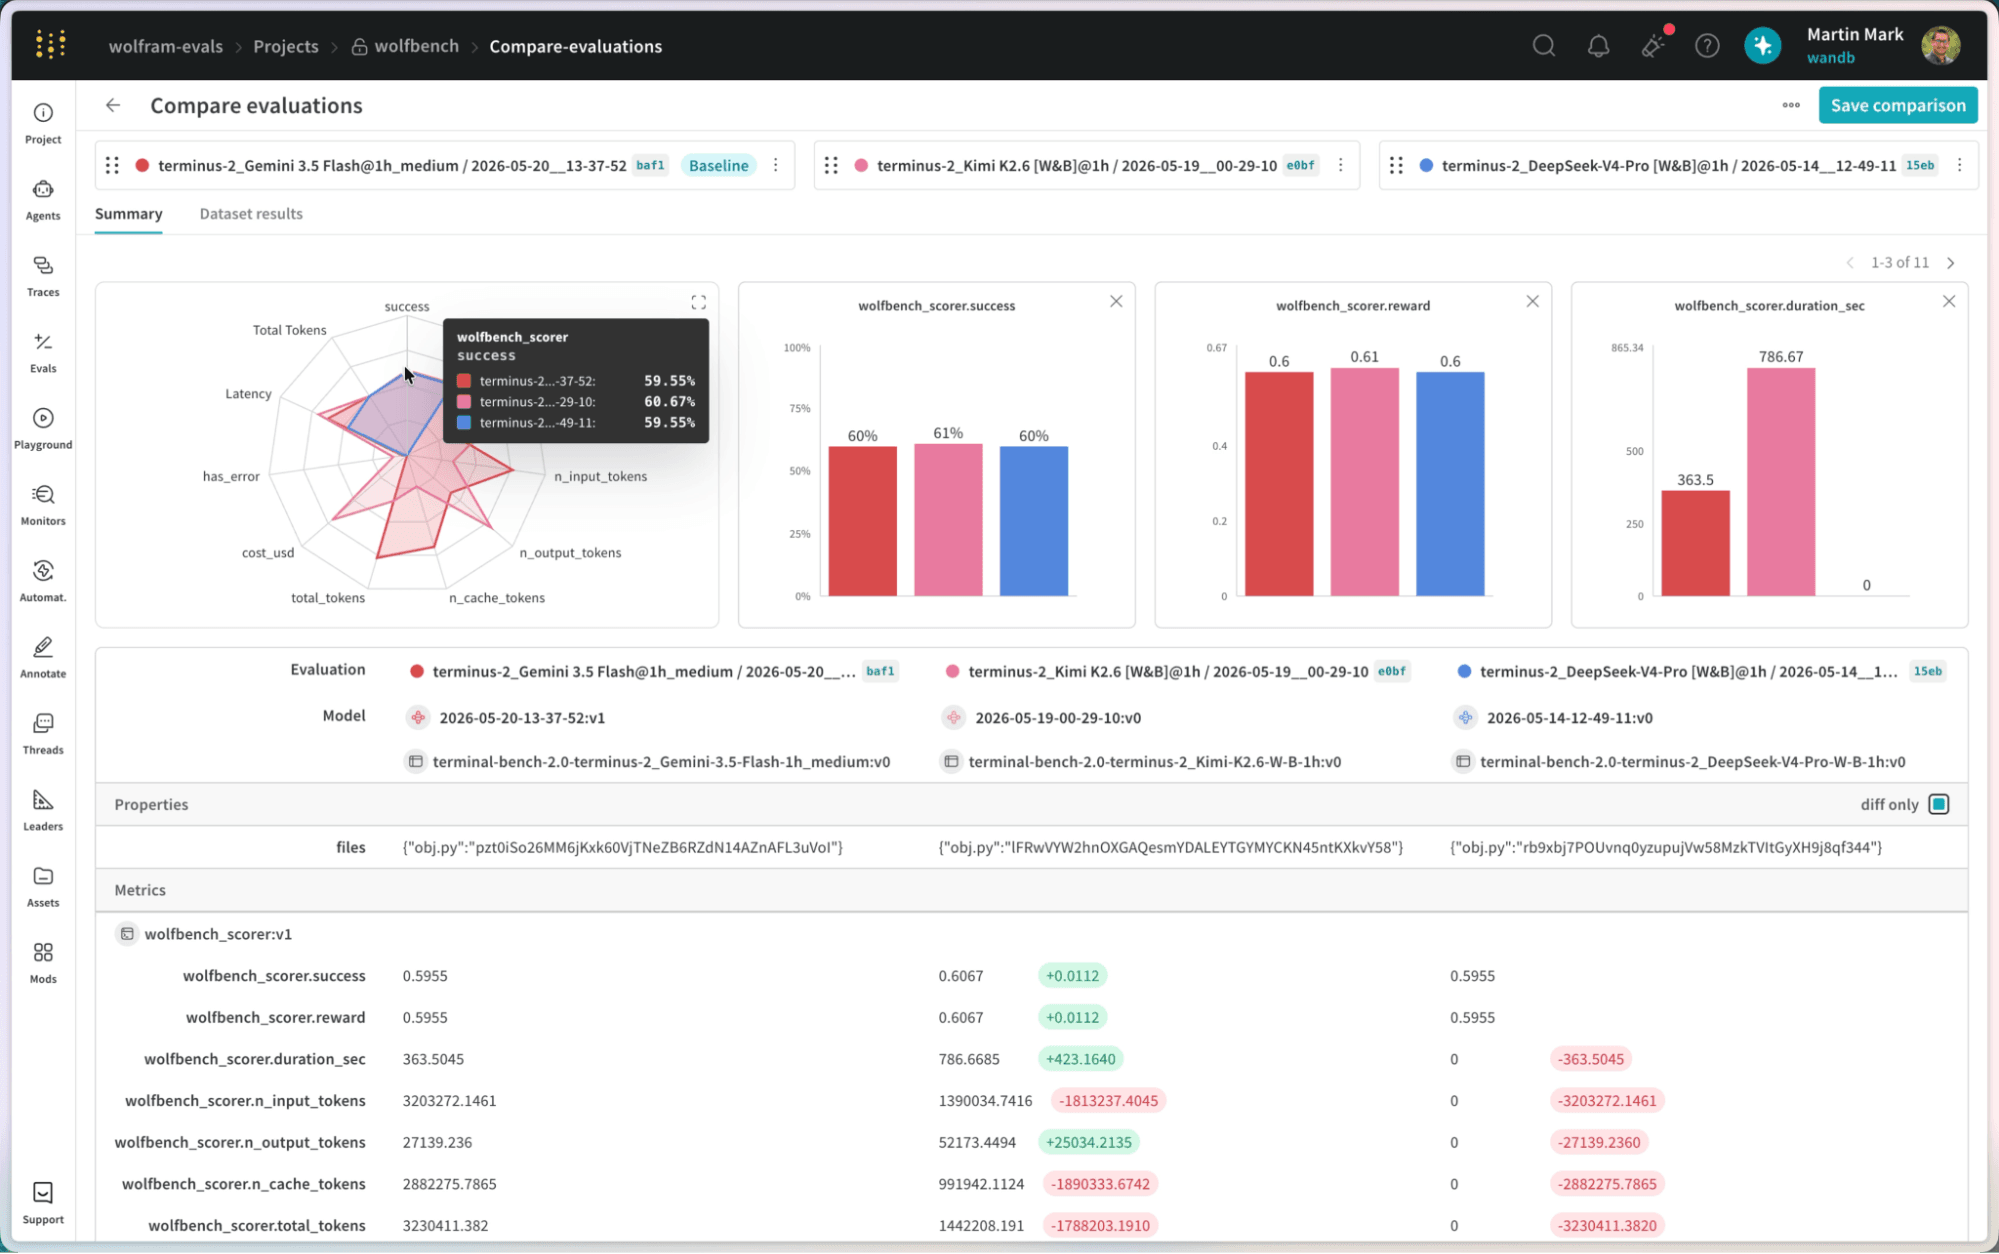
Weave also covers the standard eval workflow – LLM-as-a-judge, custom scorers, human feedback with automatic versioning across runs – plus evaluation workflows that can be wired into CI/CD, though release-blocking gates typically require custom workflow logic.
The real difference from Braintrust is what surrounds Weave: model training, fine-tuning, experiment tracking, and LLM monitoring share one platform, so teams running both traditional ML and LLM workloads keep everything in one place.
Key features
Agent tracing: Automatically log every session, turn, step, and tool call with first-class agent semantics built into the data model.
Production signals: Built-in and custom signals automatically capture and classify agent interactions to surface failure modes without manual trace review.
Evaluations: Measure output quality through LLM-as-judge, custom scorers, or human feedback, with automatic versioning across runs.
CI/CD integration: Run evaluation suites on every pull request and block merges when quality metrics regress.
Cost analytics: Automatically calculate token usage and estimated spend using Weave's built-in LLM cost estimator.
ML and LLM continuity: W&B Models and Weave share the same platform, connecting model training, fine-tuning, and LLM application monitoring in one place.
How does W&B Weave compare to Braintrust?
Main differences between W&B Weave and Braintrust
- Weave connects LLM application monitoring directly to ML model training and experiment tracking. Braintrust is LLM-only.
- Weave's built-in production signals automatically surface failure modes across millions of traces. Braintrust requires manual evaluation setup.
- Braintrust's eval-first CI workflow and dataset management are more tightly integrated. Weave's eval framework is comprehensive but secondary to its observability focus.
Main similarities between W&B Weave and Braintrust
- Both offer LLM and agent tracing with inputs, outputs, token usage, cost, and latency.
- Both support LLM-as-judge evaluation and dataset management.
- Both have CI/CD integration for running evaluation suites.
- Both have a free tier of 1 GB and support OpenAI, Anthropic, and other major providers.
- Both support human feedback collection and annotation workflows.
Why do companies use W&B Weave?
According to reviews on Reddit, companies use W&B Weave because:
Setup is genuinely frictionless: A few lines of code and a decorator is all it takes to get LLM monitoring running. Evaluations and dataset management follow the same pattern.
It covers agent traceability without overcomplicating things: Weave handles agent traceability well, and most users find it does exactly what it promises.
W&B delivers more than a product: The platform goes beyond tooling, codifying an entire AI development strategy that connects model training, evaluation, and production monitoring end to end.
Bottom line
W&B Weave is the strongest Braintrust alternative for engineers already on the W&B platform who need ML experiment tracking and LLM observability unified in one place.
7. Confident AI
- Founded: 2024
- Similar to: Braintrust, LangSmith, Opik
- Typical users: Engineering, QA, and product teams building and evaluating LLM applications
- Typical customers: Mid-size and enterprise teams shipping AI features, including Panasonic, Toshiba, BCG, and CircleCI
What is Confident AI?
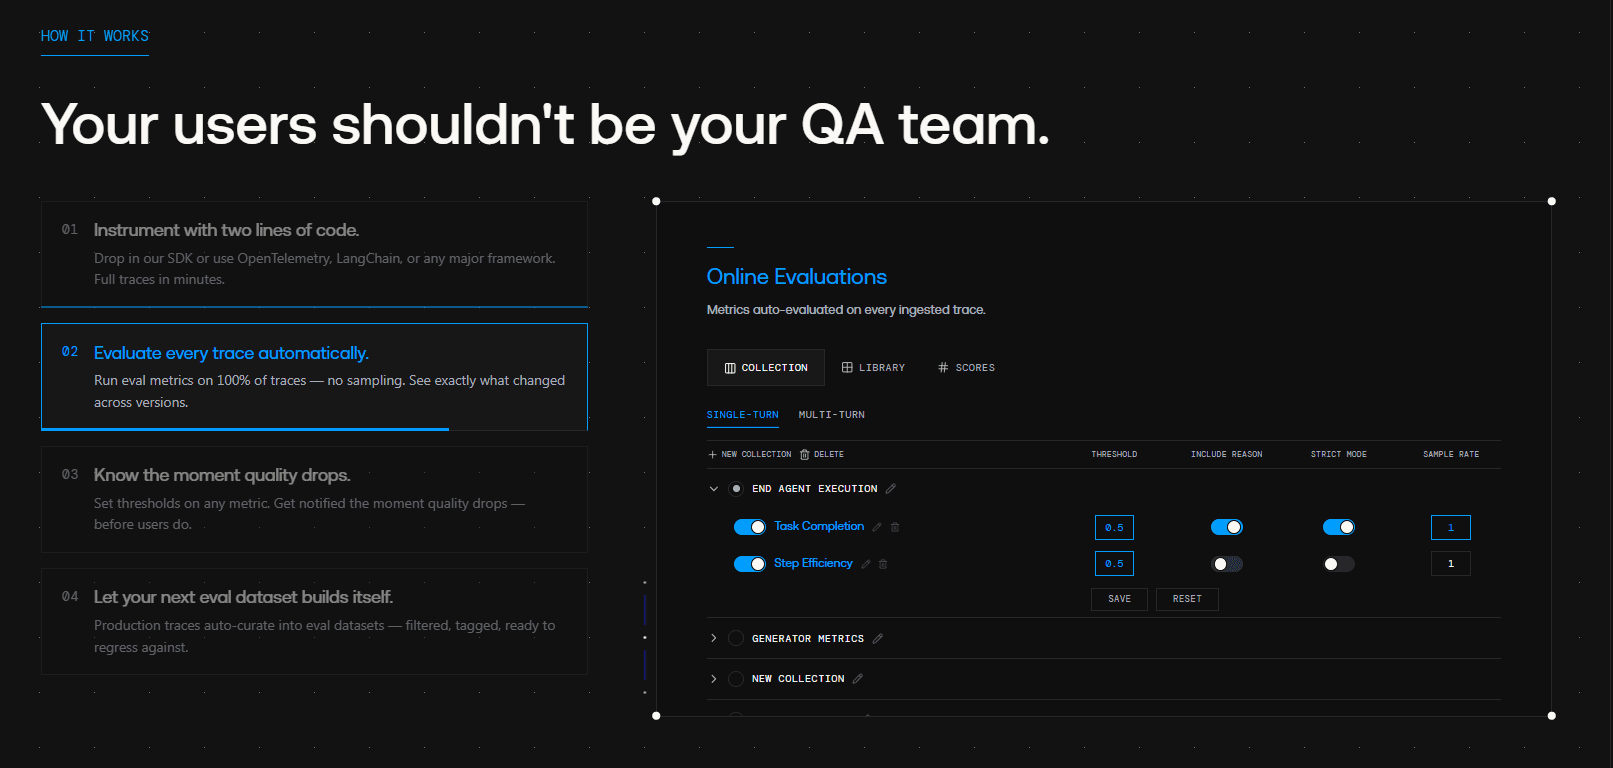
Confident AI is an LLM evaluation and observability platform backed by Y Combinator and built by the creators of DeepEval, the most widely used open-source LLM evaluation framework. Every production trace is scored against 45+ research-backed metrics open-sourced through DeepEval, covering agents, chatbots, RAG pipelines, safety, and multi-turn conversations.
The distinctive design choice is who gets to run evals. Where most platforms assume an engineer is driving, Confident AI exposes evaluation workflows through an HTTP-based interface that PMs, QA, and domain experts can own directly – curating datasets from production traces, running experiments, and reviewing results without filing a ticket.
It also monitors continuously rather than on demand: every production trace gets scored, alerts fire when quality drops below thresholds (not just when latency spikes), and multi-turn simulation generates realistic conversations with tool use and branching paths for testing conversational AI before it ships.
Against Braintrust, the two are the most eval-obsessed platforms on this list, but they're organized around different loops. Braintrust is built for the engineering loop: prompt iteration, CI gates, deploy blocking. Confident AI is built for the quality loop: continuous scoring in production, owned by whoever owns quality, which is sometimes not the person who owns the code.
Key features
45+ research-backed metrics: Every production trace is scored against research-backed metrics covering faithfulness, hallucination, relevance, bias, toxicity, tool selection accuracy, and more.
Cross-functional evaluation: PMs, QA, and domain experts can own and run evaluation workflows directly through an HTTP-based interface.
CI/CD regression testing: Block deployments when evaluation scores fall below defined thresholds on every pull request.
Production-to-eval pipelines: Curate datasets directly from production traces and run experiments without manual setup.
Quality-aware alerting: Alerts trigger when evaluation scores drop below thresholds, not just when latency spikes, with integrations for PagerDuty, Slack, and Teams.
Multi-turn simulation: Generate realistic multi-turn conversations with tool use and branching paths for testing conversational AI.
How does Confident AI compare to Braintrust?
Main differences between Confident AI and Braintrust
- Confident AI enables PMs and QA to run evals independently via HTTP. Braintrust evaluation workflows require engineering involvement.
- Braintrust's prompt iteration and CI-gated deploy workflow is more mature. Confident AI focuses on continuous quality monitoring.
- Confident AI scores every production trace with research-backed metrics. Braintrust requires a manual evaluation setup.
- Confident AI's tracing costs $10 per month plus $1 per GB. Braintrust's Pro plan costs $249/month with $3/GB overages.
- Braintrust has Brainstore, a purpose-built trace database. Confident AI uses standard cloud infrastructure.
Main similarities between Confident AI and Braintrust
- Both offer LLM tracing with inputs, outputs, token usage, cost, and latency.
- Both support LLM-as-judge evaluation and dataset management.
- Both have CI/CD integration for blocking deployments on quality regressions.
- Both have a free tier and usage-based pricing.
- Both support OpenAI, Anthropic, and other major LLM providers.
Why do companies use Confident AI?
According to reviews on Gartner Peer Insights and customer stories, companies use Confident AI because:
Evaluation cycles shrink from days to hours: A single improvement cycle that previously took 10 days now takes three hours, with product managers running it themselves.
It saves hundreds of hours of manual evaluation: Confident AI saves hours of manual AI evaluation every month, giving teams the data to defend every quality decision.
The dashboard is accessible to non-technical users: The interface is clean, well-structured, and easy to navigate, with AI-driven analytics providing clear, data-backed recommendations.
Bottom line
Confident AI is the strongest Braintrust alternative for cross-functional teams that want every production trace scored and evaluation workflows accessible to PMs and QA without engineering involvement.
Which Braintrust alternative should you choose?
- Want LLM observability connected to product analytics, session replay, and user behavior? Choose PostHog.
- Need open-source self-hosting with broad framework support and no licensing fees? Go with Langfuse.
- Building on LangChain or LangGraph? LangSmith is the natural fit.
- Want OpenTelemetry-native tracing, or ML and LLM monitoring on one platform? Pick Arize Phoenix.
- Need open-source LLM observability with real-time evaluation and automated agent optimization? Try Opik by Comet.
- Already using W&B for ML experiment tracking? Stick with W&B Weave.
- Want every production trace scored, with eval workflows accessible to PMs and QA? Confident AI is built for that.
Is PostHog right for you?
Here's the (short) sales pitch.
We're biased, obviously, but we think PostHog is the right Braintrust alternative if:
- You want AI observability connected to product analytics, session replay, feature flags, experiments, and more in one platform
- You need to understand not just what your LLM is doing, but how users are interacting with your AI features and where they drop off
- You want open-source, usage-based pricing with no per-seat charges and a generous free tier.
It's completely free to get started – no credit card required. Our setup wizard handles configuration in minutes, or you can check out our docs to do it yourself.
Install PostHog with one command
Paste this into your terminal and make AI do all the work.
Frequently asked questions
PostHog says it makes your product "self-driving" – what does that mean?
It means PostHog digs through your product data, finds what's worth fixing, and has agents do the work.
It starts with context. A full suite of developer tools – AI Observability, Product Analytics, Session Replay, Feature Flags, Experiments, Error Tracking, Logs, and more – captures everything happening in your product, and a Context Warehouse unifies it into one source agents can read across.
From there, Scouts read across all of it and sort what's worth knowing from what's just noise. What clears the bar becomes a report in your inbox: an agent picks it up, roots out the cause, and opens a PR. You review and merge.
You can steer it from Slack, the web app, the desktop app, or your own editor via the MCP or CLI.
What is the difference between AI observability and AI evals?
AI observability answers "what is my system doing in production?" capturing traces, latency, token counts, errors, costs, and user interactions.
AI evals answer "is my system producing good outputs?" scoring responses against defined quality criteria, running test datasets, tracking regressions, and blocking deploys.
The two are complementary. The best platforms connect both so observability data feeds evaluation.
What is Braintrust used for?
Braintrust is an AI evaluation and observability platform for teams shipping LLM-powered features to production.
Core use cases include logging production traces, running CI-integrated evaluations, managing prompts, and curating test datasets, all of which are stored in Brainstore, a purpose-built database designed for AI trace data.
Why look for a Braintrust alternative?
The most common reasons are pricing, self-hosting, and scope.
Braintrust's paid Pro plan jumps from a generous free tier straight to $249/month with no middle option. Self-hosting requires an enterprise contract.
And if your primary need is LLM observability integrated with product analytics and user behavior, rather than a specialist eval platform, Braintrust's tight focus works against you.
How do these tools charge?
Every tool on this list bills differently, which makes price comparisons slippery. Here's the overview:
| Tool | Bills by | Free tier | First paid step | Watch out for |
|---|---|---|---|---|
| Braintrust | GB of processed data | 1 GB (~1M spans), 14-day retention | $249/month Pro (5 GB) | No middle tier between free and $249; $3/GB overages |
| PostHog | Events | 100K AI events/month | Usage-based, no base fee (from $35 per 100K, dropping to $6 per 100K at high volume) | Event count scales with instrumentation depth |
| Langfuse | Units (traces + observations + scores) | 50K units/month, hard cap | $29/month Core + $8 per 100K units | Eval scores count as billable units |
| LangSmith | Seats + traces | 5K traces, 1 seat | $39/seat/month + $2.50 per 1K traces | Costs grow with headcount; base retention is 14 days |
| Arize Phoenix | Free self-host; cloud by spans | 25K spans/month (cloud) | Cloud paid tiers vary | Self-hosting is free but you run the infrastructure |
| Opik | Spans | 25K spans/month, unlimited users | $19/month | Self-hosting is free with no caps |
| W&B Weave | Usage-based | Usage-based free tier | Varies | Pricing tied to broader W&B platform plans |
| Confident AI | Seats + data | Free tier available | $19.99/seat/month + $1/GB-month tracing | Per-seat pricing – a 5-person team is ~$100/month before data |
Is there a free or open-source Braintrust alternative?
Several.
- PostHog is MIT-licensed with 100k LLM observability events/month free.
- Langfuse is MIT-licensed and fully self-hostable with no usage caps.
- Arize Phoenix is source-available under Elastic License 2.0 and free to self-host.
- Opik by Comet is Apache 2.0 with a free cloud tier of 25K spans/month.
For more alternatives, check out our guide to the best open-source LLM observability tools.
Can PostHog replace Braintrust?
Yes, for most teams. If your primary need is production AI observability – traces, costs, evals, prompt management – connected to product analytics, session replay, and user behavior, PostHog covers it, and adds a layer Braintrust doesn't have at all: measuring whether your AI features actually moved product metrics.
Where PostHog can't replace Braintrust yet is the deep end of the eval workflow: CI-integrated quality gates, dataset curation, and deployment blocking on score regression – but PostHog ships fast and is actively working on closing the gap.
Which Braintrust alternative is best for evals specifically?
LangSmith is the best fit for LangChain and LangGraph teams.
Confident AI has the broadest eval metric coverage with 45+ research-backed metrics open-sourced through DeepEval.
Opik has a strong real-time online evaluation.
PostHog supports LLM-as-a-judge and code-based evals on production generations.
For pure eval depth with CI-integrated quality gates, Braintrust itself remains the strongest option in the space.
What is the cheapest Braintrust alternative?
For self-hosted options, Langfuse, Arize Phoenix, and Opik are all free to run on your own infrastructure.
For cloud options, PostHog is free up to 100K AI events per month with usage-based pricing after that – no monthly base fee, so low-volume months cost little or nothing.
For a full breakdown of free tiers, billing models, and how costs compare at different volumes, see our guide to the cheapest AI observability tools.
Which Braintrust alternative is best for multi-step agent tracing?
LangSmith has the deepest agent tracing for LangGraph, including time-travel debugging and step-by-step execution trees.
W&B Weave rebuilt its agent tracing from the ground up in June 2026, adding first-class session, turn, and step semantics.
Arize Phoenix is strong on multi-step agent tracing with OpenTelemetry-native span capture across tool calls, retrieval steps, and sub-agents.
Is Braintrust worth the price?
It depends on your use case. The $249/month Pro plan makes sense for teams with three or more engineers shipping LLM features where eval regressions are costly and systematic quality gates justify the investment.
For teams whose primary need is pure observability rather than eval-first workflows, cheaper alternatives like Langfuse at $29/month or PostHog's free tier cover most of the same ground.
Is there a self-hosted Braintrust alternative?
Several. Langfuse self-hosts via Docker Compose or Helm under the MIT license. Arize Phoenix runs locally with a single pip install or via Kubernetes. Opik self-hosts via Docker under Apache 2.0.
For more alternatives check out our guide to the best open-source LLM observability tools.

Subscribe to our newsletter
build mode
Read by 75,000+ founders and builders
We'll share your email with Substack
PostHog is the leading platform for building self-driving products. With a full suite of developer tools – AI observability, product analytics, session replay, feature flags, experiments, error tracking, logs, and more – PostHog captures all the context agents need to diagnose problems, uncover opportunities, and ship fixes. A data warehouse and CDP tie it all together, unifying that context into one source agents can read across. You can steer it all from Slack, the web app, the desktop (PostHog Desktop), or your own editor via the MCP.